-
Technology
-
Industry
-
Solutions
-
- ASSET MANAGEMENT
- CUSTOMER EXPERIENCE MANAGEMENT
- CYBER SECURITY
- DATA CENTER
- DOCUMENT MANAGEMENT
- ELECTRONIC DATA INTERCHANGE
- ENTERPRISE DATA MANAGEMENT
- ENTERPRISE RESOURCE PLANNING
- ENTERPRISE RISK MANAGEMENT
- ENTERPRISE-GRADE WEB DATA SOLUTIONS
- FACILITY MANAGEMENT
- FIELD SERVICE
- IDENTITY AND ACCESS MANAGEMENT
- INFRASTRUCTURE
- IT SERVICE MANAGEMENT
- MANAGED IT SERVICES
- PAYMENT AND CARD
- PROJECT MANAGEMENT
- SOFTWARE TESTING
- STORAGE
- VIDEO SOLUTIONS
- WORKFLOW
-
-
Platforms
-
Functions
- Leadership Perspectives
- Innovation Insights
- Research
- Magazines
- News
- CXO Awards




Contributory Virtus Investment Partners on the invitation from our Editorial

East West Hospitality
Blake Fleischer, PhD, Director of Data Science and AnalyticsAI in Production: Why Discipline Matters More Than Capability
Blake Fleischer, PhD, Director of Data Science and Analytics
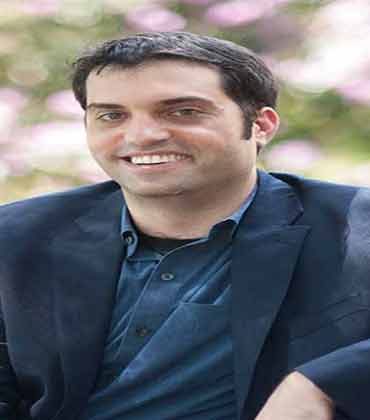
Blake Fleischer
Building on a background spanning applied machine learning, high-performance computing, and data systems architecture, I lead data science and analytics at East West Hospitality. Over the past two years, our team has completely rebuilt our core data systems while integrating AI throughout. All our work is grounded in our company culture, which emphasizes accountability, ownership, and a consistent standard of doing the right thing, not just what is easiest or fastest. Our approach to AI development reflects that same discipline, with clear ownership of outcomes and a focus on what holds up under real-world conditions where demand far outpaces team resources.
As AI capabilities have advanced, their role in our work has shifted from assistive tooling toward deeper integration into how we design and build data systems. These capabilities have expanded access to data for a broader set of users, including less technical audiences, and accelerated development in meaningful ways. At the same time, it has increased the surface area for error. The same systems that can generate useful outputs quickly can also produce results that appear correct but are not. More context does not reliably produce better outcomes, and increased access does not reduce the need for judgment. In practice, this has led to a simple realization: the limiting factor for AI in production is not capability, but operational discipline.
 The limiting factor for AI in production is not capability, but operational discipline.

What has proven most effective for us is not a particular tool or model; we rely on a set of operating principles that govern how AI is used to build and evolve production systems. Within our data team, these principles are applied consistently and include:
• Own the output: Each of us is responsible for all systems and updates we introduce, and once in production, that responsibility is shared across senior members of the team.
• Low trust/no trust: Outputs that are novel or non-obvious are treated as untrusted until independently validated.
• Build feedback loops early: Test-driven approaches are used wherever possible to validate behavior continuously, not post-hoc.
• Learn from verified output: Model suggestions, once validated, are used to refine systems, improve workflows, and identify better approaches over time.
Consistently applying these principles in everything we do helps provide a practical safeguard against failures that are difficult to detect, particularly when outputs appear coherent and plausible.
We’ve also found that time-honored software development best practices are all the more important, such as incremental changes, testing and validation at each step, and expanding from a stable foundation. Simplicity consistently outperforms unnecessary complexity. Approaches that attempt to do too much too early become difficult to maintain and harder to intuitively understand, especially when AI is involved. Treating data systems as code plays an important supporting role, allowing us to apply standard engineering disciplines, such as version control, testing, and structured review, while providing a consistent environment for AI to assist development. This combination enables faster iteration, but within boundaries that preserve reliability.
One constraint that has become increasingly apparent as our systems have grown is a form of context degradation, or a gradual decline in effectiveness as the amount of context required to operate within a system continues to expand. While often discussed in terms of model inputs, this dynamic is highly present in development environments as codebases, documentation, and workflows, especially when scaling up. In practice, it shows up as a tension between three factors:
• The ability to work effectively within short, focused (automated) interactions with AI systems.
• The size and complexity of the underlying codebase and data systems.
• The need to periodically refactor code and reorganize documentation so that both humans and models can operate efficiently.
As we build on prior work, the effect becomes more pronounced. Managing it has reinforced another practical takeaway: the challenge today is not how much AI can process, but how well the context is structured.
As organizations continue to expand access to AI and data, these dynamics are poised to become increasingly prevalent. Increasing the number of users and use cases increases both potential value and potential for error. AI does not remove the need for human judgment; it shifts where judgment is applied and makes operational discipline essential. Like previous waves of technological change, there are clear benefits to be realized, which depend heavily on understanding how these tools perform in practice. The real advantage comes not from adopting them quickly, but iterating reliably and consistently within the constraints of real-world systems.
The articles from these contributors are based on their personal expertise and viewpoints, and do not necessarily reflect the opinions of their employers or affiliated organizations.
EDITOR'S Choice

Fortune Brands Innovations [NYSE: FBIN]
By Juan Guerrero, Director, IT Audit & Data Analytics
The IT Audit Evolution: From Compliance to Strategic Intelligence
Broad River Retail
Wes Dudley, Senior Vice President, Customer Experience
Customer Experience in the Age of Amplified Complexity
Fortune Brands Innovations [NYSE: FBIN]
Scott Barnes, Sr. Director of Enterprise Cyber Security (CISO)
The X-Factor in Cybersecurity: AI and Automation at Work

LHarris Technologies [NYSE: LHX]
Brian Allred, Director of Business Intelligence and Analytics
The Shift from Rigid Dashboards to Conversational Analytics
Ivar's Restaurants
Patrick Yearout, Director of Innovation, Recruitment & Training
From Hiring to Development: Nurturing Teams that Care