-
Technology
-
Industry
-
Solutions
-
- ASSET MANAGEMENT
- CUSTOMER EXPERIENCE MANAGEMENT
- CYBER SECURITY
- DATA CENTER
- DOCUMENT MANAGEMENT
- ELECTRONIC DATA INTERCHANGE
- ENTERPRISE DATA MANAGEMENT
- ENTERPRISE RESOURCE PLANNING
- ENTERPRISE RISK MANAGEMENT
- ENTERPRISE-GRADE WEB DATA SOLUTIONS
- FACILITY MANAGEMENT
- FIELD SERVICE
- IDENTITY AND ACCESS MANAGEMENT
- INFRASTRUCTURE
- IT SERVICE MANAGEMENT
- MANAGED IT SERVICES
- PAYMENT AND CARD
- PROJECT MANAGEMENT
- SOFTWARE TESTING
- STORAGE
- VIDEO SOLUTIONS
- WORKFLOW
-
-
Platforms
-
Functions
- Leadership Perspectives
- Innovation Insights
- Research
- Magazines
- News
- CXO Awards


This article is part of CIOReview's Innovation Insights series featuring expert contributions nominated by our subscribers and reviewed by our editorial team.
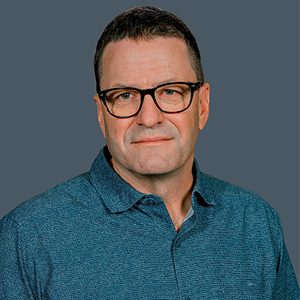
Why Generic AI Benchmarks Can't Tell You If Your Translations Are Enterprise-Ready
What two years of testing Opal against frontier models and commodity MT on real enterprise content taught us about continuous benchmarking, enterprise AI and why the model alone was never the right thing to measure.
Every few months, a new large language model claims to be the best in the world at translation. The claim usually rests on a leaderboard score, BLEU, COMET, a win rate on FLORES-200 or the WMT shared task. For an enterprise deciding how to localize a product, a support center or a regulatory filing into ten languages, those scores answer only part of the question. They do not reveal what happens to approved terminology, brand voice, placeholder tags or client-specific style preferences once AI is applied to real production content. Nor do they indicate whether the model leading today's benchmark will still be the strongest choice six months from now, after the next frontier model arrives. Most importantly, they were almost certainly never tested on an organization's own content in the first place.
That distinction has become increasingly important as enterprise AI matures. Organizations are no longer asking whether large language models (LLMs) outperform traditional machine translation. Instead, they are asking how to evaluate those models, how to deploy them and how to ensure quality continues to improve as both models and business requirements evolve. The challenge is building a repeatable process that continually identifies the best approach for a specific organization, its content and its languages.
At Welo Global, our AI translation platform, Opal, was built around the assumption that the only benchmark worth trusting is one built from real enterprise content, scored by professional linguists and refreshed continuously as models change. That assumption shaped the Opal Benchmark program, which has evaluated frontier language models, commodity machine translation engines and multiple enterprise translation workflows across seven enterprise accounts, ten locales and a wide range of production content. Running Opal Benchmark 2.0 and 2.1 has reinforced a broader lesson that extends beyond translation. In a market where the underlying models continue to evolve at an unprecedented pace, benchmarking itself is becoming a strategic capability.
Generic AI Leaderboards Answer the Wrong Question
Academic benchmarks such as FLORES-200 and the WMT shared task have played an important role in advancing translation research, but they were never designed to guide enterprise technology decisions. They compare research systems using curated datasets, largely drawn from publicly available sources such as Wikipedia and news content, under controlled testing conditions. That makes them valuable for measuring scientific progress. It does not necessarily make them reliable predictors of production performance.
Two challenges, in particular, limit their usefulness for enterprise evaluation. First, today's frontier models perform so closely on many public benchmarks that separating the leaders often comes down to marginal differences. Because benchmark datasets have circulated widely throughout the AI community, much of that content has also likely influenced model training, making leaderboard gains increasingly difficult to interpret. Second, automated evaluation metrics such as COMET, while representing a significant improvement over older methods like BLEU, still inherit limitations from the human judgments used to train them. A translation can read fluently while introducing factual errors, violating approved terminology or confidently producing output that simply does not belong in production.
 The objective is not to prove that yesterday's architecture was correct. It is to ensure tomorrow's architecture is better.

None of those benchmarks tells an enterprise buyer whether a product name survives translation, whether currency and address formats localize correctly or whether a broken placeholder tag is about to take down a website. Those are precisely the issues that determine whether AI translation succeeds in production, yet they rarely appear in generic leaderboards.
Measuring What Matters in Enterprise Translation
Those realities require a different approach to benchmarking. Rather than evaluating models on generic sentences, Opal Benchmark measures translation quality using actual production content from enterprise customers, including product documentation, marketing copy, support articles, technical specifications and HR content. Benchmark 2.0 evaluated more than 113,000 production segments automatically while also conducting detailed human evaluation across a curated sample of approximately 8,000 words. Thirty professional linguists, working independently across ten target locales, assessed translation quality using consistent evaluation criteria that reflected real production expectations rather than academic test conditions.
The benchmark compares every major translation approach under identical conditions. Commodity machine translation engines, including Google Translate, Amazon Translate and DeepL, are evaluated alongside Opal's AI-powered post-editing pipeline (AIPE), which can operate on generic MT, trained MT or translation memory input and Opal's LLM-mode, which combines frontier language models with enterprise-specific prompts, style guides and client-specific translation-pair injection. Where supported, external systems were configured using their available enterprise capabilities, including client-specific glossaries, to ensure each platform was evaluated under comparable production conditions. The objective is not simply to determine which model scores highest on a benchmark. It is to understand how different translation workflows perform when applied to the types of multilingual content enterprises publish every day.
The evaluation itself extends well beyond a single quality score. Every translated segment is assessed against a taxonomy of seven error categories and twenty-seven subtypes, including mistranslation, terminology violations, clarity and idiomaticity, punctuation and spacing, locale-specific formatting, "do-not-translate" violations and placeholder corruption that can silently break a production website. Linguists also rank competing systems against one another, providing both an overall quality assessment and a detailed diagnosis of why one system performs better than another.
This level of analysis produces something generic leaderboards cannot. Rather than asking which model performs best in the abstract, it reveals how enterprise translation systems perform against the quality standards that matter in production.
The Results Matter, but the Process Matters More
The first question any enterprise should ask is straightforward. Before comparing prompting strategies or workflow configurations, does an enterprise translation platform outperform the alternatives organizations would otherwise use?
Across Benchmark 2.0, the answer was unambiguous. Every Opal configuration outperformed every external, non-Opal system in the human evaluation, often by a substantial margin. Opal LLM-mode running Claude Opus 4.6 achieved top-tier rankings on 71.5% of evaluated segments while receiving below-podium rankings only 13.4% of the time. Even the lowest-performing Opal configuration outperformed the strongest external machine translation engine included in the study.
Automatic evaluation across the full 113,000-segment dataset reinforced the same conclusion. Every Opal workflow scored ahead of every external provider. Commodity machine translation engines appeared in the lowest quality tier approximately 2.6 times as often as Opal's strongest configuration, produced roughly 1.6 times more errors per translated segment and generated significantly more terminology violations. The results demonstrate that enterprise-specific assets, including terminology, translation memories, style guides and production workflows, continue to provide measurable quality improvements beyond what a foundation model can achieve on its own.
Those findings are important, but they were not the most interesting outcome of the benchmarking program. The more significant lesson emerged only after the testing continued. As new frontier models entered the market, the answer to which configuration performed best began to change. The benchmark was no longer identifying a single winning model. It was demonstrating why enterprises need a repeatable process for continuously measuring quality as models, languages, content types and customer requirements evolve.
Why the Best Model Keeps Changing
Perhaps the most important lesson from running successive Opal benchmarks is that there is no permanent winner. The strongest-performing model today is unlikely to remain the strongest performer indefinitely and the pace of change continues to accelerate.
Benchmark 2.0 demonstrated that Opal's LLM-mode running Claude Opus 4.6 consistently delivered the highest quality across every evaluated enterprise account. It produced error-free translations nearly half the time, outperforming both commodity machine translation engines and Opal's own AI-powered post-editing workflows. Six months later, however, Benchmark 2.1 told a different story. GPT-5.5 had narrowed the gap enough to match or exceed the previous leader while reducing overall error volume substantially. At the same time, another frontier model showed measurable advantages for specific language pairs, particularly Japanese and Korean, yet those gains were too small to justify the significantly higher operating cost for most production scenarios.
The conclusion is straightforward: selecting a model is not a one-time architectural decision. It is an ongoing optimization problem. Perhaps the biggest lesson from two years of benchmarking is that the honest answer keeps changing. Which model performs best depends on the client, the language, the content type and the moment in time.
The picture becomes even more nuanced when examining enterprise content across languages, locales and customers. Different languages expose different weaknesses. French translations may require greater attention to fluency and idiomatic phrasing, while Italian content can reveal more locale-specific formatting issues. Non-Latin-script languages such as Japanese, Korean, Chinese and Russian consistently produce wider quality gaps between competing systems than many Western European languages. Enterprise customers also behave differently. One customer may achieve the best results with the newest frontier model, while another continues to perform better using a highly optimized translation engine refined over years of production data.
That variability changes the nature of enterprise AI evaluation. Organizations are no longer searching for the best model. They are determining which model performs best for a particular customer, content type, language and business objective at a particular moment in time.
When More AI Doesn't Produce Better AI
One assumption appears repeatedly throughout discussions about enterprise AI. If adding AI improves quality, then adding even more AI should improve it further.
Benchmark 2.1 challenged that assumption directly. Within Opal, we tested whether combining a custom-trained machine translation engine with the strongest available frontier model would outperform running that same frontier model through Opal's LLM-mode alone. Importantly, neither workflow represented a raw API call. Both configurations used Opal's orchestration layer, prompting framework, client-specific terminology, style guides and enterprise controls. The only meaningful difference was whether an additional trained machine translation stage preceded the frontier model.
The additional translation stage did not improve quality. Instead, the simpler workflow produced fewer errors overall while outperforming the more complex pipeline in direct comparisons. Rather than validating every component of an existing architecture, the benchmark demonstrated that one long-standing assumption no longer held true for today's frontier models.
That finding illustrates why benchmarking cannot become a marketing exercise designed only to confirm previous engineering decisions. A mature evaluation program should identify what works, what no longer works and where complexity has stopped creating value. Some enterprise assets continue to deliver measurable improvements. Translation memory matches remain highly effective. Client-specific translation examples measurably improve model output. Carefully constructed style guides continue to reduce terminology and consistency errors. Long-trained machine translation engines may still outperform frontier models for specific customer accounts.
Other components, however, may no longer justify their cost once frontier models become sufficiently capable. Knowing the difference requires measurement rather than intuition.
The Harness is the Product
For Opal, that orchestration layer includes routing logic, structured prompts, client-specific translation examples, terminology injection, style guidance, quality controls and production guardrails. Together, these components transform a general-purpose language model into an enterprise translation system tailored to the needs of individual organizations.
Equally important, the benchmark determines which parts of that orchestration continue adding value and which should evolve as the underlying models improve. Without continuous measurement, engineering teams risk accumulating unnecessary complexity simply because previous architectures once performed well. Benchmarking provides objective evidence for simplifying workflows when new models eliminate the need for older components, while preserving specialized capabilities that continue delivering measurable quality improvements.
In that sense, the benchmark functions less as a report card and more as an engineering feedback loop. Every evaluation informs future routing decisions, workflow design, prompt engineering and enterprise customization. The objective is not to prove that yesterday's architecture was correct. It is to ensure tomorrow's architecture is better.
Continuous Benchmarking Is the Competitive Advantage
The only safe assumption is that the underlying models will continue changing. Costs will fluctuate and new reasoning architectures will emerge. Some models will excel in particular languages, while others will prove stronger for specific enterprise workflows.
None of those changes eliminate the need for benchmarking. They increase it. For enterprises, translation quality failures rarely appear as abstract benchmark scores. They appear as broken placeholder tags that prevent a website from rendering correctly, incorrect terminology in regulated documentation, untranslated interface elements or inconsistent product messaging across global markets. These are the production failures organizations actually pay to avoid and they are exactly the types of errors that enterprise benchmarking is designed to measure.
Economics reinforce the same conclusion. Each new generation of frontier models generally carries higher operating costs than the one before it. Organizations should not automatically deploy the newest model across every language, every customer and every content type simply because it exists. Instead, they need evidence showing where those additional costs produce meaningful improvements and where existing workflows continue delivering comparable results.
Rather than relying on manually defined routing rules, future enterprise translation systems will increasingly use accumulated benchmark data to automate model selection itself. As evaluation datasets grow organizations can make increasingly precise decisions about which model, prompt, workflow and quality controls should be applied to each translation request. Continuous benchmarking becomes the training signal that enables
Ultimately, the competitive advantage will not belong to the organizations using the newest model. It will belong to the organizations that continuously measure quality, adapt their workflows and refine their routing as better models emerge. In that sense, benchmarking is no longer simply validating enterprise AI. It is becoming one of the core capabilities that makes enterprise AI successful.
MORE FROM INNOVATION INSIGHTS
Welo Global
Chris Grebisz, CTO
Why Generic AI Benchmarks Can't Tell You If Your Translations Are Enterprise-Ready
CFBD
Carlos Barrientos Di Liberto, CEO & Milagros Evelin Ortiz Minaya, CFO, CFBD
Video Analytics: Innovation and Market Challenges
Outabox
Darren Blinn, Executive Director, Business Operations
The Connected Casino: Why the Future of Gaming Technology Is Integration, Not Replacement
EXPLORE OUR KNOWLEDGE NETWORK
The articles from these contributors are based on their personal expertise and viewpoints, and do not necessarily reflect the opinions of their employers or affiliated organizations.
